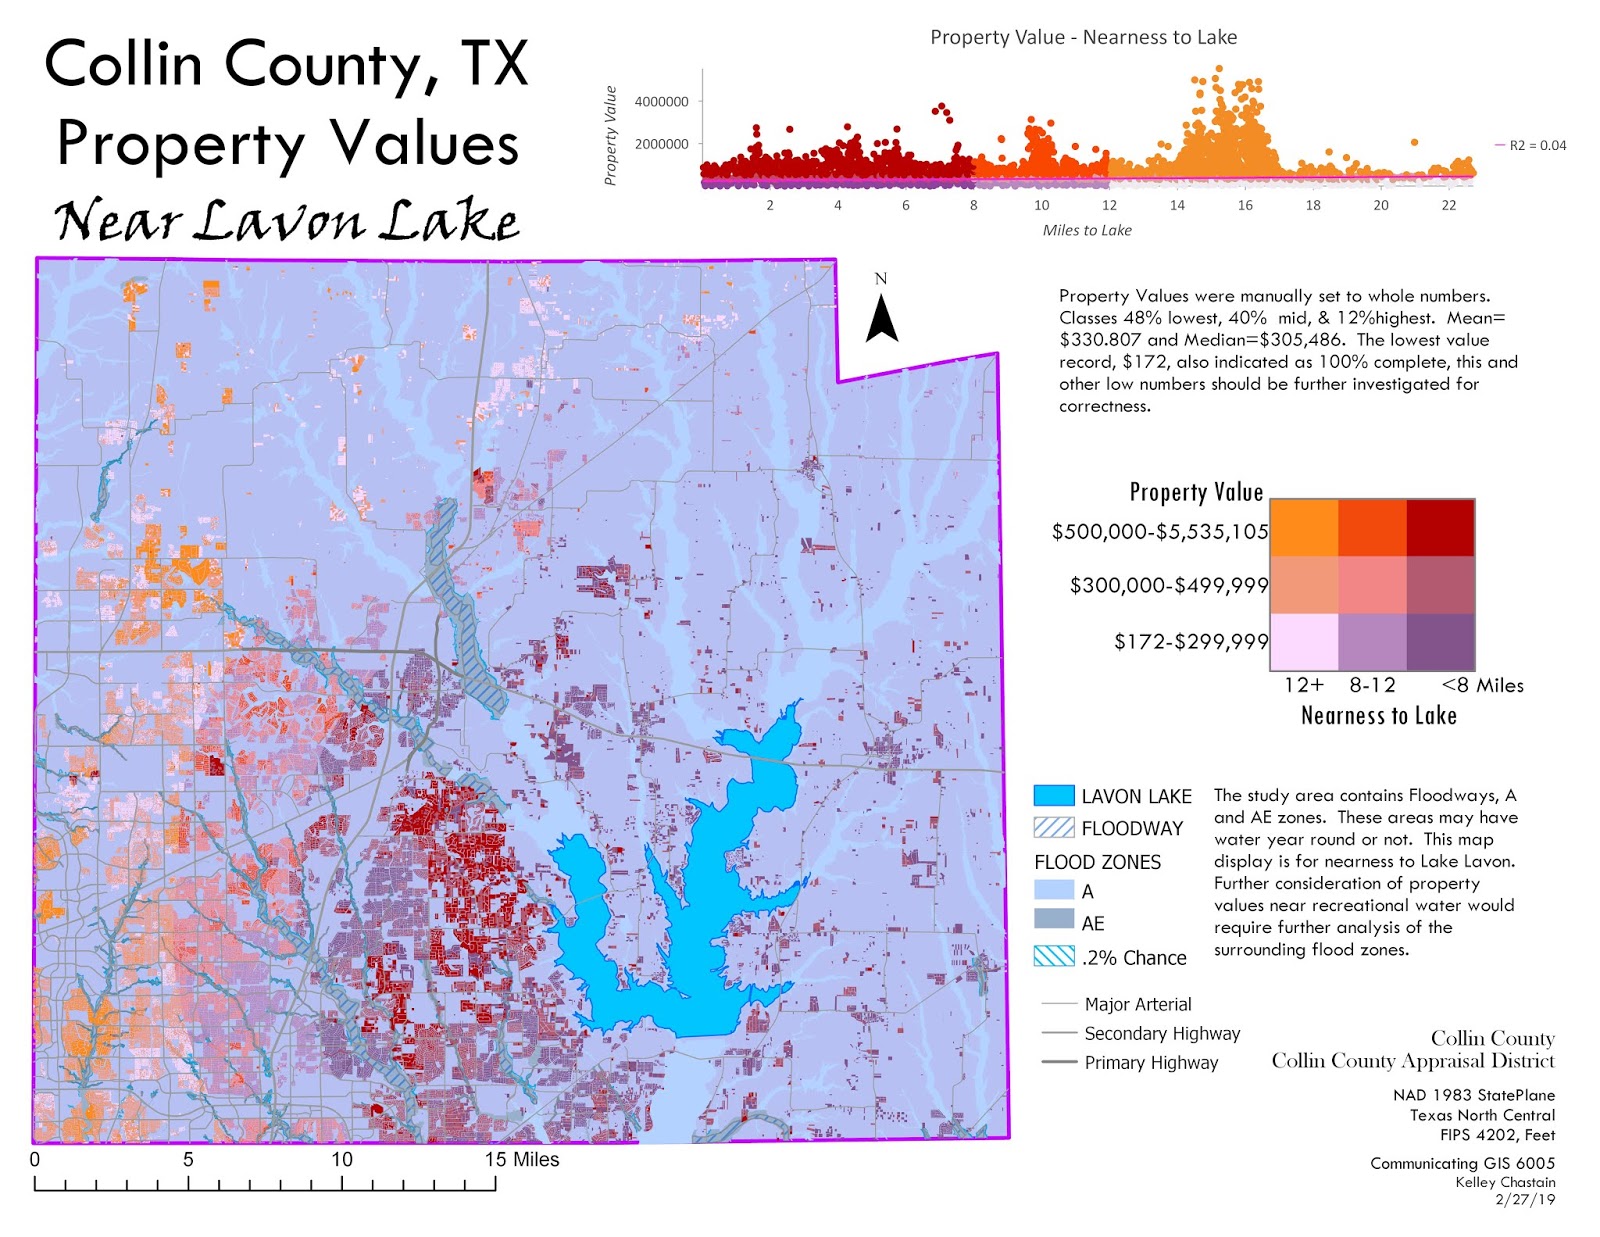
My second infographic includes a scatter plot and bivariate choropleth. The scatter plot displays distance to lake on the x axis and property values on the y axis. The bivariate choropleth displays property value in a 3 class manual display (< $300,000 = 48.0%, $300,000-$500,00 = 40.0% and above $500,000 11.8%) and nearness to Lavon Lake in a 3 class quantile class (rounded to whole numbers: <8 miles = 36.68%, 8-12 miles = 31.5%, more than 12 miles = 31.82%). The two variable legend classes from lower left as furthest from the lake (more than 12 miles and lowest property values at under $300,000. to the highest lass upper right with nearest to the lake (within 8 miles) and property values over $500,000. This display would indicate there is not a significant correlation between the two variables. This may be due to the floodplain in the area containing floodways that may contain year round navigable waters, allowing access to recreational waters in areas other than the lake.
Friday, March 1, 2019
Final Project: Collin County Residential Property Value
My final project for Communicating GIS 6005 was to examine limited variables correlation to single family property values in Collin County, Texas. The variables considered were number of bedrooms, number of bathrooms, age of property and nearness to Lavon Lake. Shapefiles for Lavon Lake boundary, Collin County boundary, roads, and floodplain boundary were obtained from Collin County. Parcel data was obtained from Collin County Appraisal District. The above infographic contains scatter plots for property value on the x axis and number of bathrooms (top) and number of bedrooms (bottom). The age of the properties are displayed on purple with a black to white color ramp displaying oldest to newest properties. The main display is of assessed property values shown on a color ramp from dark blue to bright yellow (low-high). The main display also includes the floodplain for the area. Finally in the main display, low in the hierarchy, are primary highways, secondary highways and major arterial roads. Parcel data was limited to single family residential that were 100% complete and contained information on bathrooms, bedrooms and assessed property value. Data should be further examined as the property values range from 172 to over $5.5 million. Those properties of very low values should be examined for error.
Sunday, February 17, 2019
Module 6: Proportional Symbol and Bi-variate Choropleth
Proportional symbol mapping is a quantitative map that varies the representation of a feature, and the size, shape, and color vary with the particular variable. This type of map is very appropriate to map data counts.
Our first assignment was to utilize a proportional symbol map to represent the population size of cities in India. First we were asked to determine the appropriate variables for a custom conic projection for the area. I utilized a central meridian of 80E and parallels of 30.8N and 12.0N. The symbol properties for the proportional symbol were set with consideration of the background colors and visibility. Finally a custom legend was created to show the range of symbols utilizing Flannery Appearance Compensation to accentuate the differences in the larger symbols.
Next we moved on to divergent proportional symbology to display jobs gained or lost by state in a time frame of December 2007 and July 2015. This map creation had many challenges. First the use of negative numbers does not work for this process. The original shape file was divided into two shape files utilizing Select by Attribute SQL for <0 and >0. In the file with the data <0, a new field was created, the field calculator was utilized to obtain the absolute value of those numbers (essentially making them positive). Due to technical difficulties with loading this data (load times were extreme for even the smallest changes), and the two layers (gains and losses) being set to the same minimum size, line width, and no maximum created different size reference I tried to make the map as completely basic as possible. I am not satisfied with this map, but in the time frame and technical issues this is it.
Update: Due to the technical issues with ArcPro with proportional symbol for raw count data that I encountered for the above map, I chose to change the symbolization for the raw count data to a dot density map. More confident in the display of the data in this format.
Finally, we were asked to create a bi-variate choropleth map displaying two variables (% obesity and % physical inactivity) Bi-variate choropleth maps display two variables (sometimes three = Tri- or Multi-variate) on the same map. Variables for choropleth maps should be normalized. These were in the form of %. Each variable was classed into 3 class quantile classification in order to obtain the break values for the classes. From the attribute table use of SQL to obtain the records for these classifications were then classed in new fields. The completion of a column for each variable were then combined using concatenate to a third/final field. The map was symbolized
Sunday, February 10, 2019
Module 5: Analytics
This week we downloaded 2018 County Health Rankings National Data from http://www.countyhealthrankings.org/explore-health-rankings/rankings-data-documentation
After downloading the data we were to review and choose two variables that could be related and create an info-graphic from the variables. "The County Health Rankings are based on counties and county equivalents. The data is a variety of national and state sources that are standardized and combined using scientifically-informed weights."(County Health Rankings & Roadmaps, 2019).
The objective of this lab assignment is to practice the use of a number of different data visualization techniques, including bar charts and scatter plots, as well as the design of communication materials that combine maps and other graphics. We were to select appropriate chart types for our chosen data. We then created charts for data visualization, including scatter plots, bar charts, and a pie chart. Finally, we were to combine maps, charts, and text into a single data visualization product (above).
I chose "% uninsured" and "% frequent mental distress". I was unable to determine how "% frequent mental distress" was specifically determined, but feel the relationship to Mental Illness would be close. My hypothesis was that the states with higher mental distress would also have higher uninsured rates. The correlation being that those with mental illness not able to obtain treatment due to no insurance would lead to higher mental distress incidents. The scatter plot of the two variables shows some correlation but not as strong as I had suspected. The bar charts show the high and low states for the variable as well as the national, Florida and Alabama (my specific area). The area chart illustrates how few of the population are not insured. I also included a pie chart as well as a simple graphic to show 1 out of 25.
Reference:
County Health Rankings & Roadmaps. (2019). Retrieved from: http://www.countyhealthrankings.org/explore-health-rankings/our-methods [Accessed 8 Feb. 2019].
Sunday, February 3, 2019
Module 4: Color and Choropleth
This week's project was to pick one state from a list provided and extract the state information and map the population change from 2010 to 2014. I picked Colorado. Colorado has 2 UTM zones and 3 StatePlane, so these were
eliminated as projection choices. I did not locate
a projection specific for the State of Colorado. I chose to use NAD 1983 (2011) Contiguous USA
Albers. A custom Albers projection adjusted with central
meridian and standard parallel would have been better, but I couldn’t figure
out how to change them. The formula I utilized to normalize data to percent of change
in population is: (Population 2014-Population 2010)/Population 2010*100. I used an 8 class manually assigned classification. I after looking at the natural breaks for a 5
class I decided to take the natural breaks and round them to more user friendly
intervals keeping significant breaks for both growth and loss of population. I also added a critical class for the 0 marker. I utilized a divergent color scheme to help symbolize those
that population increased/decreased. Darkening greens to indicate increased growth
and progressively darker grays for loss of population.
Sunday, January 27, 2019
Module 3 - Terrain Visualization
This week we studied terrain visualization. We considered contour lines, DEM, hillshade single and multiple light source, and color tinting. The above map utilized an elevation raster provided for Yellowstone National park and a land cover raster. The elevation raster was processed with a single light source hillshade tool from the Raster function in the Raster group of the Analysis tab in ArcPro. The land cover raster categories were generalized into fewer groups and appropriate colors were chosen for each group. The land cover layer is displayed at 45% transparency to allow the hillshade texture to show through. Legibility of the map text and message are clear. Visual Contrast is sufficient to distinguish categories but not abrasive. Figure Ground is clear between the boundaries of the land cover of Yellowstone park and the grey tones of the hillshade outside of the park. Hierarchy is demonstrated in text size and element location. Title is largest text and subtitle is smaller and more ornate. The north arrow is placed within a non-focus part of the map frame. The projections and class are in larger font and positioned above author name and date. Balance was addressed with a centered map frame and main title, large legend is balanced with other map elements.
Sunday, January 20, 2019
Module 2 - Coordinate Systems
This week in Communicating GIS we learned about Coordinates systems, Scale and Projections. For the map above we were tasked with selecting one US State other than Florida and creating a general reference map layout for that area of interest. The layout should be in a coordinate system appropriate for the state. Although State Plane and UTM projections are quite common in the US, not all states fit in a single zone of said projections. Texas has 5 State Plane zones and 3 UTM zones. Projections for UTM and State Plane are zone specific and as such neither of these would be appropriate for the state of Texas. Fortunately there are several projections that are appropriate for the entire state. I chose to use NAD 1983 (2011) Texas Centric Map System. This projections is a Lambert Conic conformal map. The central meridian is at -100. The standard parallels are at 27.5 and 35.0. This projections is specific for the state of Texas and conformal, retains shape, making it an appropriate projection for a general reference map for Texas.
Wednesday, January 16, 2019
Module 1 - Map Design and Typography
1.
Legibility:
Symbol Size, Text size and Font, color
2.
Visual
Contrast: Color choice – bright without
a different outline color against white background
3.
Figure
Ground: Color and Size and Detail – grey
for roads with labels that are smaller and lighter in text than the large event
symbol with larger font in all caps for a short name field added to attribute
table
4.
Hierarchical
Organization: Color, Size and Detail –
The focus information, location of venues have larger, darker colored symbols
with larger, black all cap labels. The
roads are not full saturation with smaller Cap/lower case labels. The golf course and water features are bold
colors not as saturated with no labels.
5.
Balance: I started with Travis county orientation on
the map, later in instructions an indication that layer was not required. I was able to enlarge the relevant data with
the elimination of Travis County boundary.
Title at the top and map elements located within the data frame around
the bottom.
The second map took an existing map designed as a conservation poster and modified to create the above report map. The elements were resized and color palate changed to highlight the report areas of interest and the harvest values added.
1.
Legibility:
Symbol Size, Text size and Font
2.
Visual
Contrast: Color choice – Wood colors of
green and brown with areas of restriction in grey against white background
3.
Figure
Ground: Color against white
4.
Hierarchical
Organization: Map is a large element of
the map. The main title is larger and
centered from the subtitle giving the location.
The legend and the company logo are roughly the same size. And the text for the lease values is large in
comparison with the other marginalia.
5.
Balance: The map frame is located to the right with
the heavy title at the top, the important information at the left and the
detail information small at the bottom.
The third project was to add typology to this reference map of San Francisco. The general features were labeled in Arial font in black and varying size. Water features were labeled in Informal Roman in Lapis blue font at differing size based on the size of the elements. Parks were labeled in a fir green Brandly Hand ITC font. The Golden Gate bridge is the only landmark labeled at Eris bold ITC font in black. The topological features labeled with California FB bold font in brown. Each of the different fonts helps tie together like features and separate those of different categories.
The fourth map was to utilize dynamic label options in ArcPro to find the best label options for the rivers in Mexico. I used Bell MT font at 11pt in Italic and Ultra Blue with .5 line width Ultra Blue outline. I chose River Placement with an offset of 1pt and checked the boxes for Measure offset from the feature geometry and May place label at secondary offset. I unchecked the box for align label to direction of line, because this would turn some labels upside down in orientation to the map.
I allowed Stack
label and selected Choose best for the Horizontal alignment and split after
space. The Maximum character per line
was set to 17. No abbreviated or Key number were
utilized. I removed duplicate
labels within 1” but repeat minimum of 2”.
Label buffer of 16% eliminated Lacantum, and some of the clutter in the
most southeast area of the map. No
minimum feature size was utilized as this eliminated Colorado label. Line connection was to connect features
Unambiguous.
Saturday, November 10, 2018
Module 10: Supervised Classification
This week we continued to look at automated classifications, focusing on Supervised Classifications. Supervised Classification requires the user to set "training sets" to guide in the separation of the pixels into classes. The objective of the training sets is to select a homogeneous area for each spectral class. Selection of multiple training sets helps to identify the many possible spectral classes in each information class of interest. Training sets can be selected by 1)digitize polygons, that have a high degree of user control but often result in overestimate of spectral class and 2)seed pixel where the user sets thresholds. Both of these methods were utilized this week in lab. Training aids help evaluate spectral class separability, for example graphical plots like histograms, coincident spectral mean plots, or scatter plots. There are also statistical measures of separability like divergence or Mahalanobis distance. Parametric distance approaches are based on statistical parameters assuming normal distribution of the clusters (mean, std deviation, co-variance). Examples of parametric methods are mahalanobis distance, minimum distance and maximum likelihood. Non-Parametric distance approaches are not based on statistics but on discrete objects and simple spectral distance (examples are feature space and parallel-piped).
In lab this week we produced classified images from satellite data. We created spectral signatures and areas of interest (AOI) features utilizing both digitize polygons and seed pixels. We evaluated signatures by with histogram plots and mean plots to recognize and limit spectral confusion between spectral signatures. We classified images utilizing maximum likelihood classification and then merged classes and calculated area.
Sunday, November 4, 2018
Module 9: Image Classification
This week we continued with image classification. Image Classification is a major application of remotely sensed imagery to provide information on land use and land cover. In a previous weeks we utilized tone, texture, shape, size, pattern, shadow and surroundings to identify and classify. Then moved on to looking at different spectral bands. This week we move toward automated procedures. Spectral Pattern Recognition is a numerical process whereby elements of multispectral image data sets are categorized into a limited number of spectrally separable, discrete classes. Unsupervised Classification, the focus this week, uses some form of clustering algorithm to decide which land cover type each pixel most looks like. Supervised Classification, next week, uses training sites from multiple spectral band data to guide the computer's classification.
Tools like Feature Space Image allows visualization of 2 bands of image data simultaneously through a 2 band scatterplot, one band plotted on the X and the other on the Y axis. This tool helps consider covariance, correlation and clustering between bands. Spectral Distance, is one means of predicting the likelihood that a pixel belongs to one class or another. Spectral Distance can be measured as simple euclidean distance in unsupervised or a statistical distance in supervised. These tools help to differentiate spectral classes, clusters of spectrally similar pixels, that can then be used to form information classes, meaningful groups.
This week in lab we performed unsupervised classification in both ArcMap and ERDAS. We attempted to accurately classify images of different spatial and spectral resolutions. And we manually reclassified and recoded images to simplify the data. We utilized ISODATA (Iterative Self-Organizing Data Analysis Technique) Clustering Algorithm.
The map this week is of the UWF campus. The main map was created by utilizing ISODATA classification in ERDAS. The tool was set to 50 classes with 25 iterations with a convergence threshold of 0.95 and a skip factor of 2 for both X & Y. Reclassification of the 50 classes to 5: trees, grass, building&roads, shadows and mix. The reclassification was then merged into the 5 classes. The lab instructions were to calculate an estimate of porous and non-porous surfaces in the image. I decided to run ISODATA with the same specifications and reclass based on porous, non-porous, and mixed. Both processes proved difficult primarily due to pixels categorized in the same groups of 50 that were different information classes. Pixels for roads, parking lots and roof tops sharing groupings with grass or bare ground. With the original 50 classes to ulizmarly get 5 classes for the main map and 3 classes for the insert the error ratio, based only on my opinion of the visual inspection, is still high.
Saturday, October 27, 2018
Module 8: Thermal Infrared
This week in Photo interpretation we learned about thermal energy. Thermal energy is heat emitted from objects. Thermal energy waves are much larger than the waves we have previously discussed. Due to the size of the waves there is very little scattering, but the range of measurable waves is limited by the atmosphere, by elements like water. Stefan-Bolzmann law states radiation increases with temperature.
In lab this week we worked between ArcMap (my ArcPro was not cooperating) and ERDAS. We learned to create composite multispectral images in both ERDAS with layer stack and ArcMap with the composite band tool.
The map deliverable shows the difference in imagery displaying different bands in different colors. I chose to look for three features recognizable by me: Interstate 10, Fairhope Pier, and the Grand Hotel. Fairhope Pier is really only discernible in the True Color display and then only when zoomed very close. The interstate gets lost under what I think are clouds in the Mobile Bay Estuary, but at least a part can be seen in the thermal layer (I think). The False Color shows clearly the areas of high vegetation in dark red wich are also the lighter areas on the Thermal display as those are cooler than the urban areas. The Grand Hotel grounds showed up very well in the False Color.
Saturday, October 20, 2018
Multi Spectral Analysis
This week in lab we gain more information about spectral bands, band ratios, spectral properties of vegetation. We explored some vegetation indices: NDVI, SAVI and EVI. And we discussed spectral enhancements in the form of Tasselled cap and Principle Components Analysis.
In lab we continue to utilize ERDAS to explore Image Histograms. We gained experience operating the inquire cursor, interpret histogram data, and identifying features by interpreting digital data.
I must admit that I am unsure of my results this week. I worked through the lab instructions and made it to the deliverable assignment and read it and thought I do not know how to do that! But I kept playing around in ERDAS. I examined the histogram, and looked at the image in gray scale and as multispectral changing the band combination. I looked at the histogram again, still not sure what I am supposed to be getting. Then I remembered the histogram X axis is the brightness and the Y axis the frequency of that brightness.So then I had some clues directing to bright objects or dark objects and how frequent. Then in grey scale I looked for changes to the imagery in different bands. And I repeated that some with the multispectral and adjusted the bands (not so much time here because I could keep trying different combinations for days). Then I utilized the Inquire Cursor to see if I had put the clues together in an area the meet the pixel values provided. I could be totally wrong on this one. But I tried to follow the clues as best I could and I came up with answers, and SOME COOL (may be correct) MAPS.
Sunday, October 14, 2018
Module 6: Image Enhancement
This week we covered Radiometric Correction or Enhancements to account for effects of sensor-detector-and platform, atmospheric and illumination effects, and terrain effects. We also looked at Spatial Enhancements with Pan-Sharpening (merging a panchromatic image at high resolution with an image at lower resolution) and spatial filters. We were presented with: types of radiometric effects that can impact remotely sensed data, differences between absolute and relative atmospheric correction, pan sharpening, convolution filter (high and low pass filters), and Fourier transform.
This week in lab we walked through the steps of downloading and importing satellite imagery from https://glovis.usgs.gov/ (which wasn't loading properly at the time), performed spatial enhancements in ArcMap and ERDAS and utilized Fourier Transform function. The goal of the above image was to restrict the striping impact of the image while keeping the detail of the image. I don't think mine is a very good example. This was much more difficult and felt more of an art than a science. The lab instructions included several enhancement techniques, a wedge mask, a low pass filter and then a sharpening. From there the direction was our own. I applied another low pass filter of 5X5 in addition to the 3X3 we used earlier and then sharpened again. The second sharpening did not seem to enhance as much as the earlier. And although the additional low pass toned down the striping I feel I lost significant detail in the process. Previous to this exercise I would have though that image correction would involve specific calculations and then transformations to correct. This was not my experience with this lab. It was more of trial and error. Maybe this changes with more experience or maybe the experiences shape the decisions of how to correct.
Sunday, September 30, 2018
Module 5a - Intro to ERDAS Imagine & Digital Data
This week in lecture we learned about Electromagnetic Radiation (EMR), models of EMR focusing on the Wave model, Electromagnetic Spectrum, EMR interactions of refraction, scattering, absorption, reflectance and transmission.
In lab this week we were exposed to ERDAS Imagine for the first time. We used basic tools to add data, fit to frame, adjust vector symbology, navigate the image, set default data directory and default output directory, and changed band combinations to examine enhancements. The project we added an area column in the attribute table in ERDAS, selected a small area of image utilizing the inquire box and created a subset of the image from the inquire box and saved to output as .img. The .img was opened in Arc Pro and the above map created to show the classes within my subset and the area of each of classes.
Subscribe to:
Posts (Atom)